Original prompt
Create a working calculator app.
Choose the technology yourself.
Run it.
Test it.
Fix any issues you find.
Do not ask me questions unless you are genuinely blocked.
计算器应用
4 runs · 12.A.01 · HTML
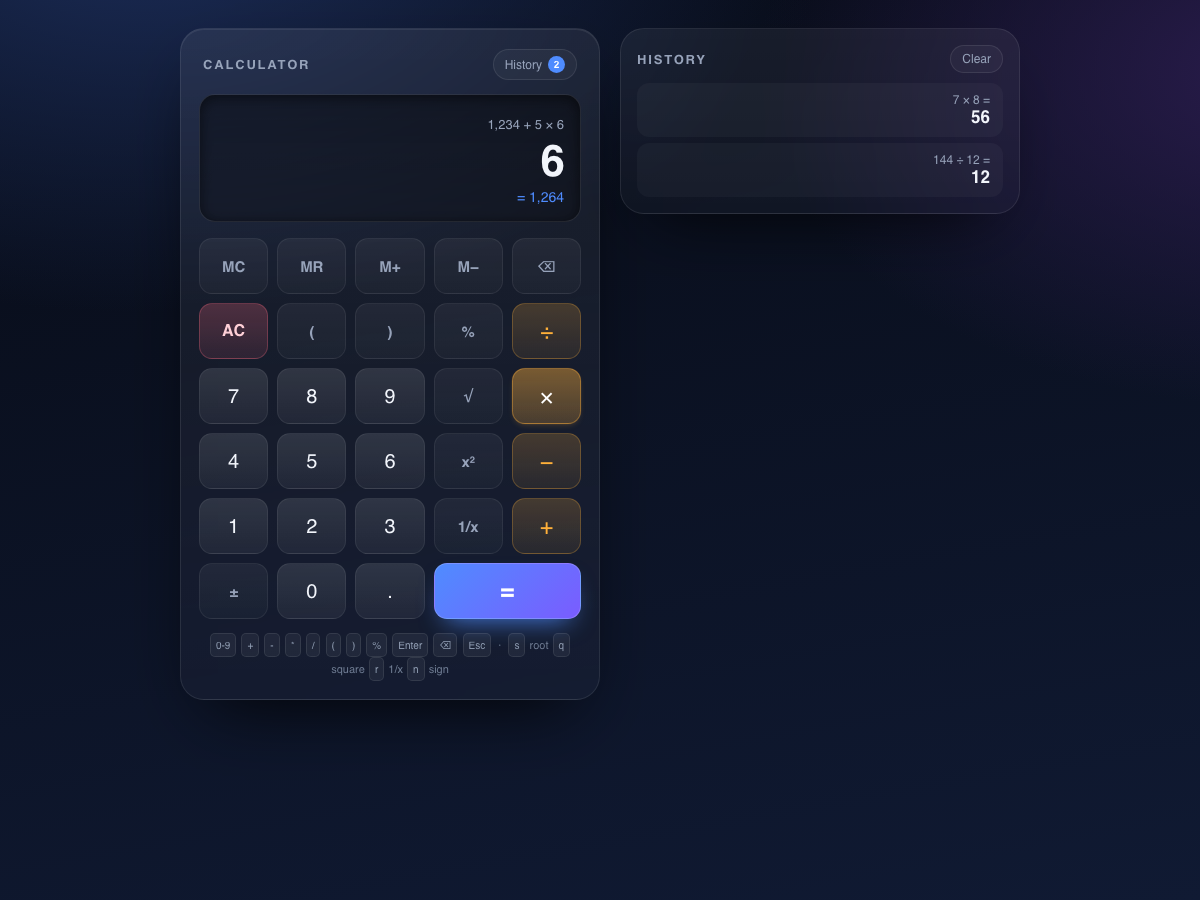
Preview note: Embedded storage and downloads can be restricted by browser sandboxing; use the standalone view for full behavior.
PROMPT/Phase1_TEST_PROMPTS_BILINGUAL.md · The original prompt is kept verbatim
Create a working calculator app. Choose the technology yourself. Run it. Test it. Fix any issues you find. Do not ask me questions unless you are genuinely blocked.
创建一个可工作的计算器应用。技术由你自行选择。运行它、测试它,并修复发现的所有问题。除非确实受阻,否则不要向我提问。
The deliverable should be a calculator application that actually runs and has been tested and repaired, using a technology stack chosen by the implementer. Minimum capabilities include digit and decimal entry, the four basic operations, clear, backspace, sign toggle, and equals. A strong implementation should also handle precedence, chained calculations, keyboard input, error states, and number formatting. The calculation core should be deterministic; division by zero, malformed expressions, overflow, and floating-point display noise should be handled intelligibly without crashing the UI. The handoff should include run instructions, a test method, and evidence that discovered defects were fixed.
All three results use the same width and the same preview ratio; no model is marked as best.
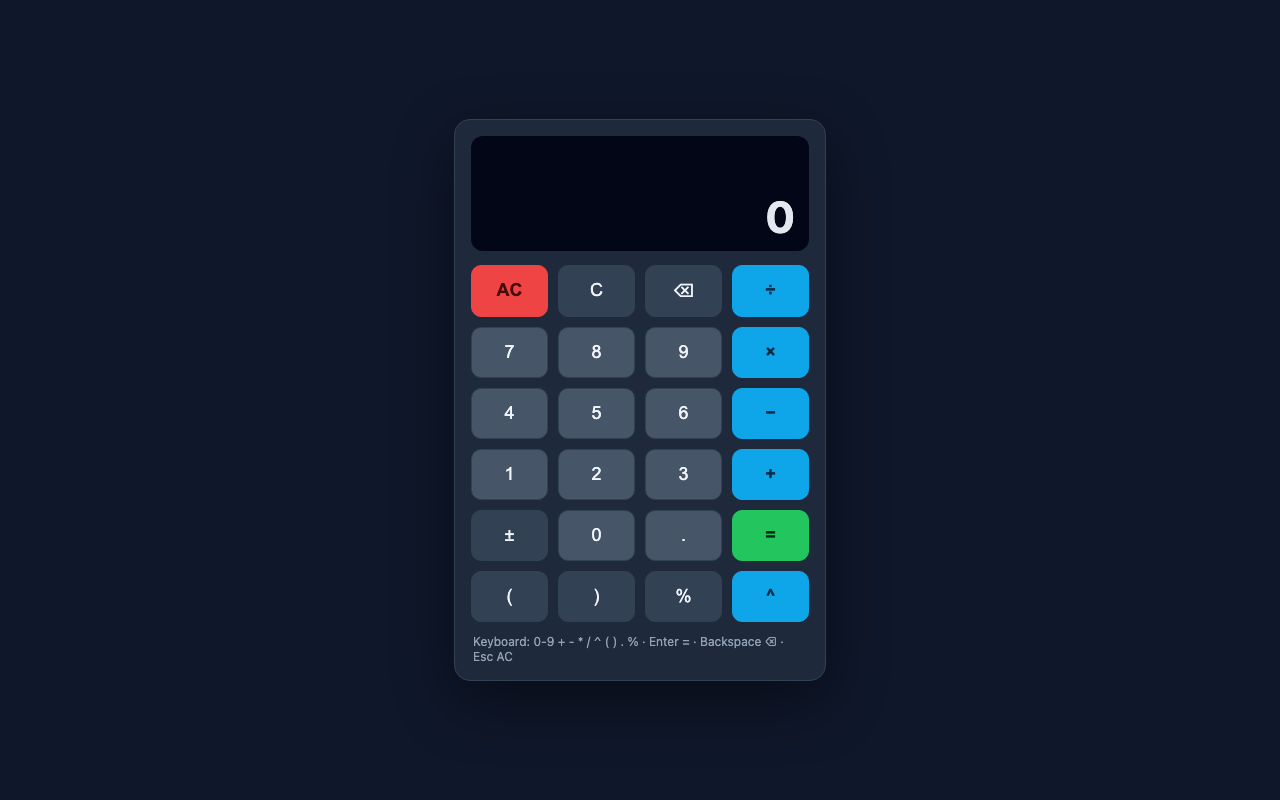
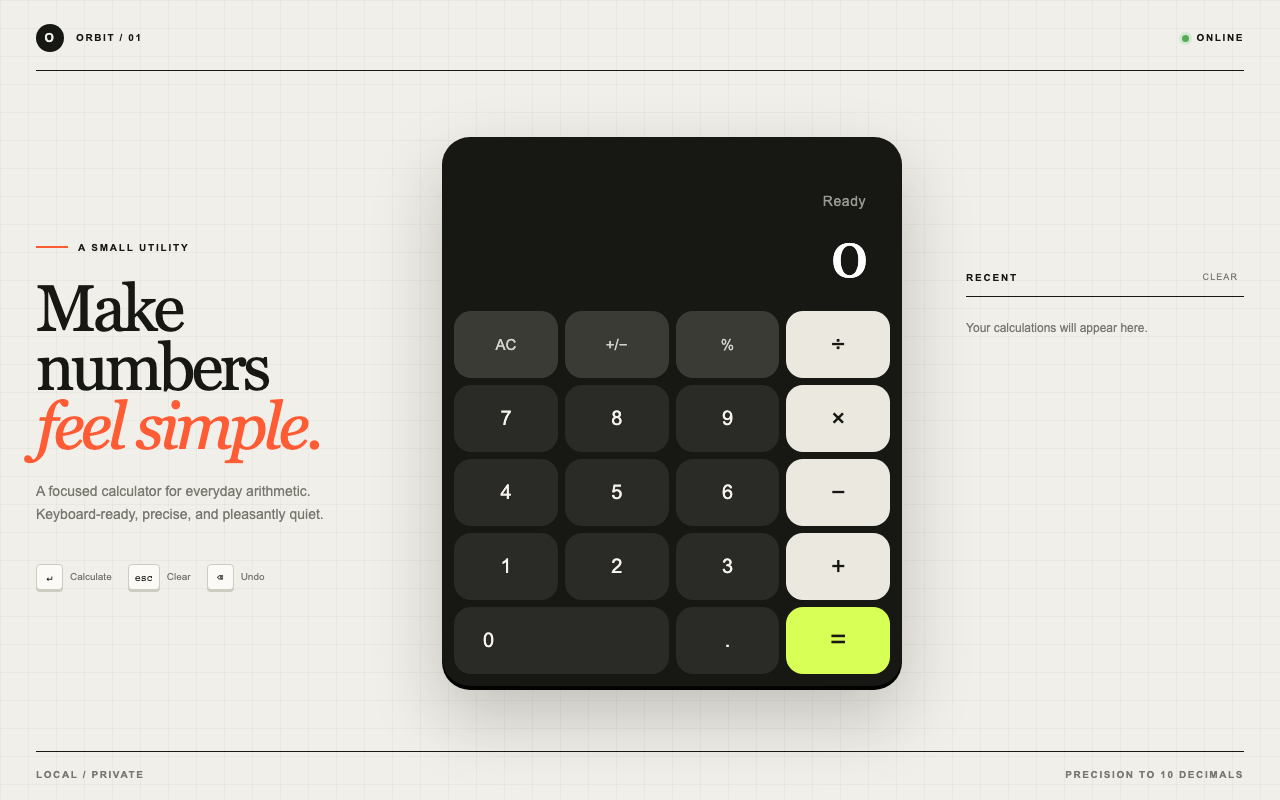
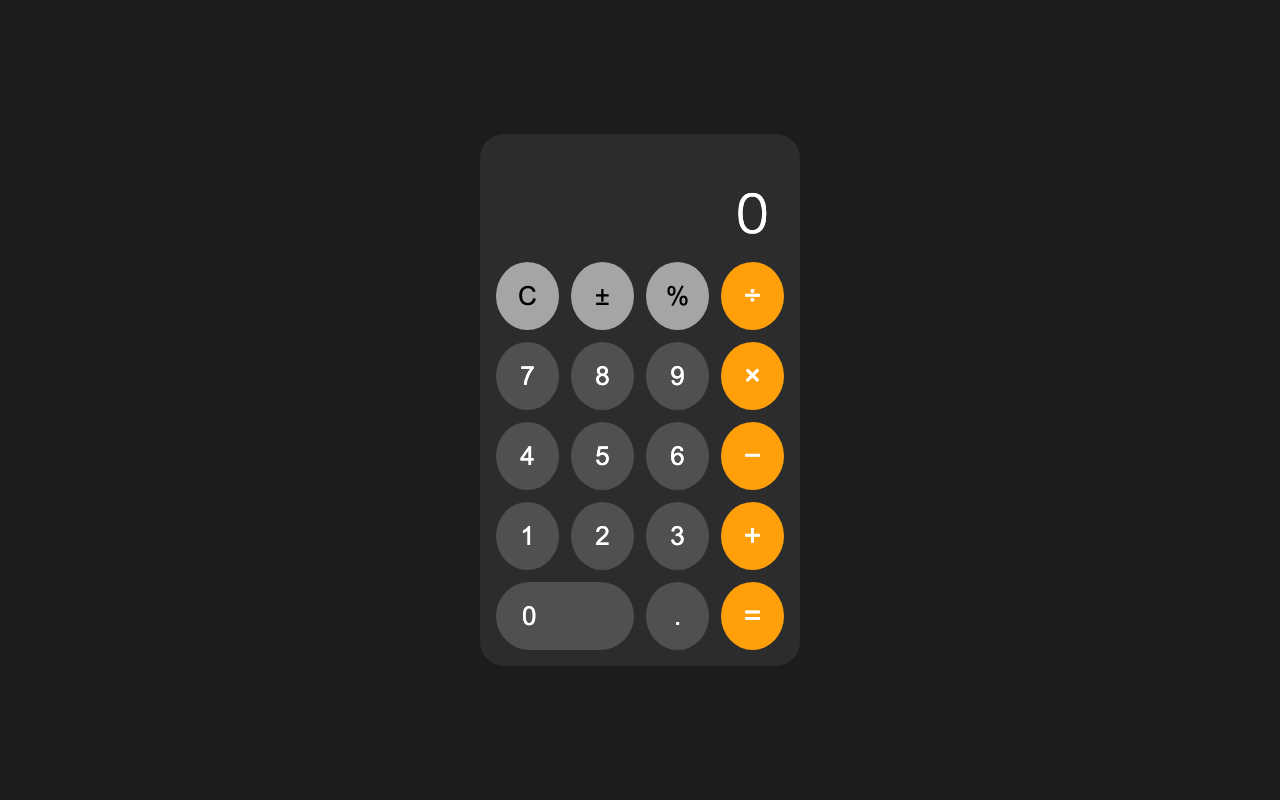
Cross-model comparison must note differences in harness, budget and isolation.
| Metric | DeepSeek-V4.1-Flashrun-deepseek-v4-1-flash-exp-0910-task-12-r1 | Muse Spark 1.3run-muse-spark-1-3-task-12-r1 | GPT-5.6 Solrun-gpt-5-6-sol-task-12-r1 | K3run-k3-task-12-r1 |
|---|---|---|---|---|
| Runtime | 6:20 | 2:00 | 6:04 | 4:05 |
| API calls | 89 | 18 | 16 | 12 |
| Tool calls | 90 | 21 | 8 | 11 |
| Failures / retries | 6 | 0 | 0 | 1 |
| Token throughput | 7.5M | 316K | 609.3K | 382.5K |
| AI review | 98/100 | 78/100 | 78/100 | 89/100 |
Two runs of the same task version can be compared side by side.
Type to search; ↑ ↓ to choose, Enter to open
No matching archive records.