01HTML
An archive of things AI models actually made.
记录模型真正创造出来的东西。
On the same task set, compare what each model actually made, how the run went, and what independent reviewers concluded.
 02 · SVG
 03 · SVG
All three results use the same width and the same preview ratio; no model is marked as best.
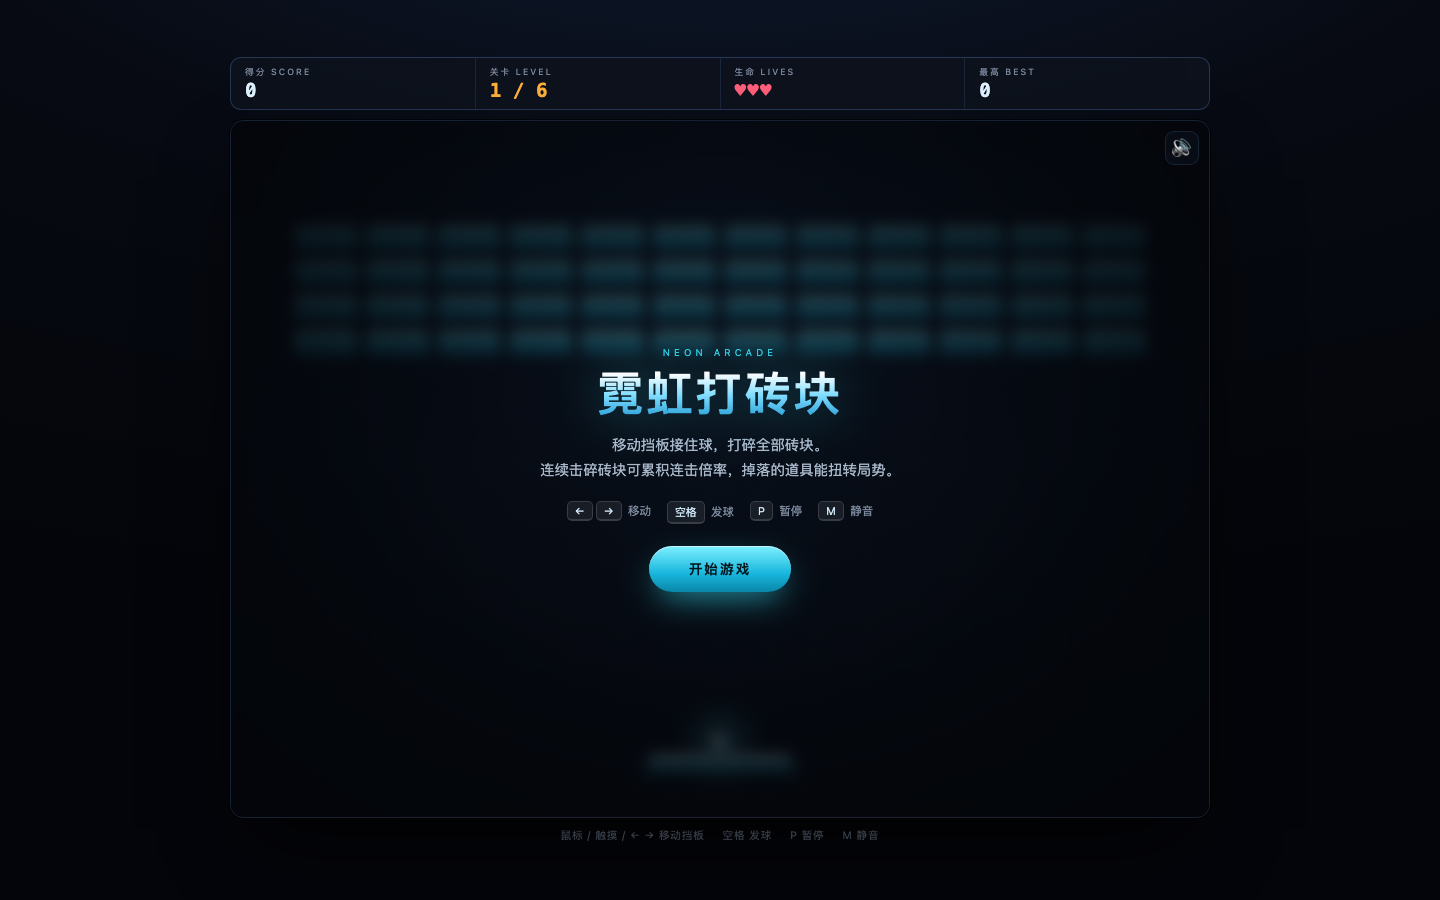
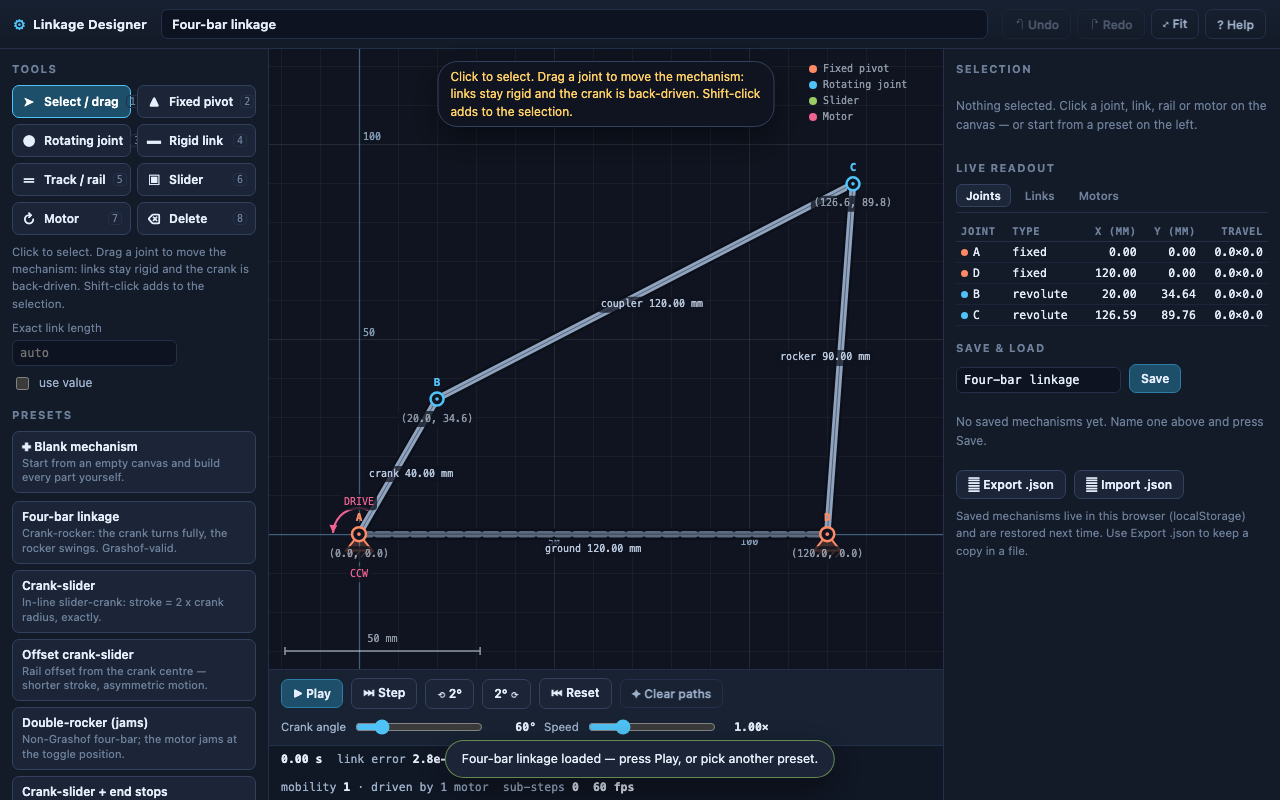
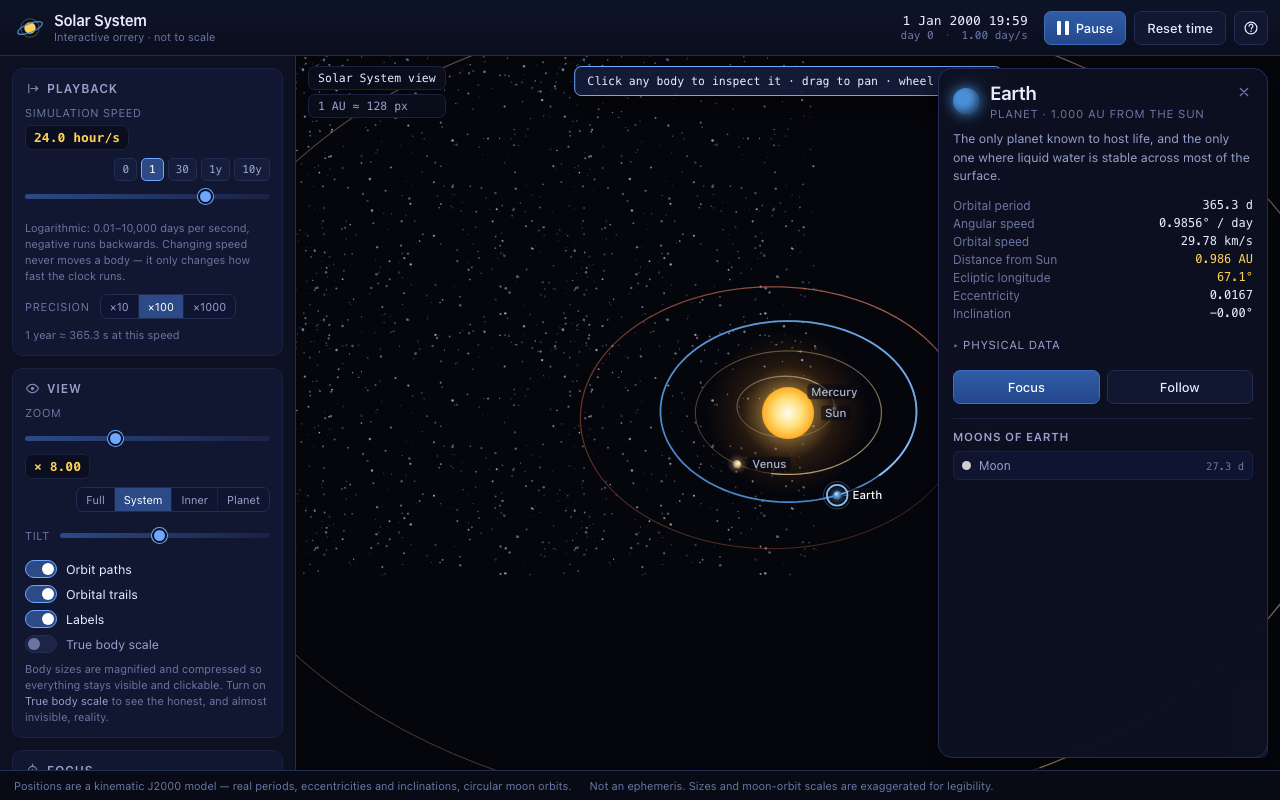
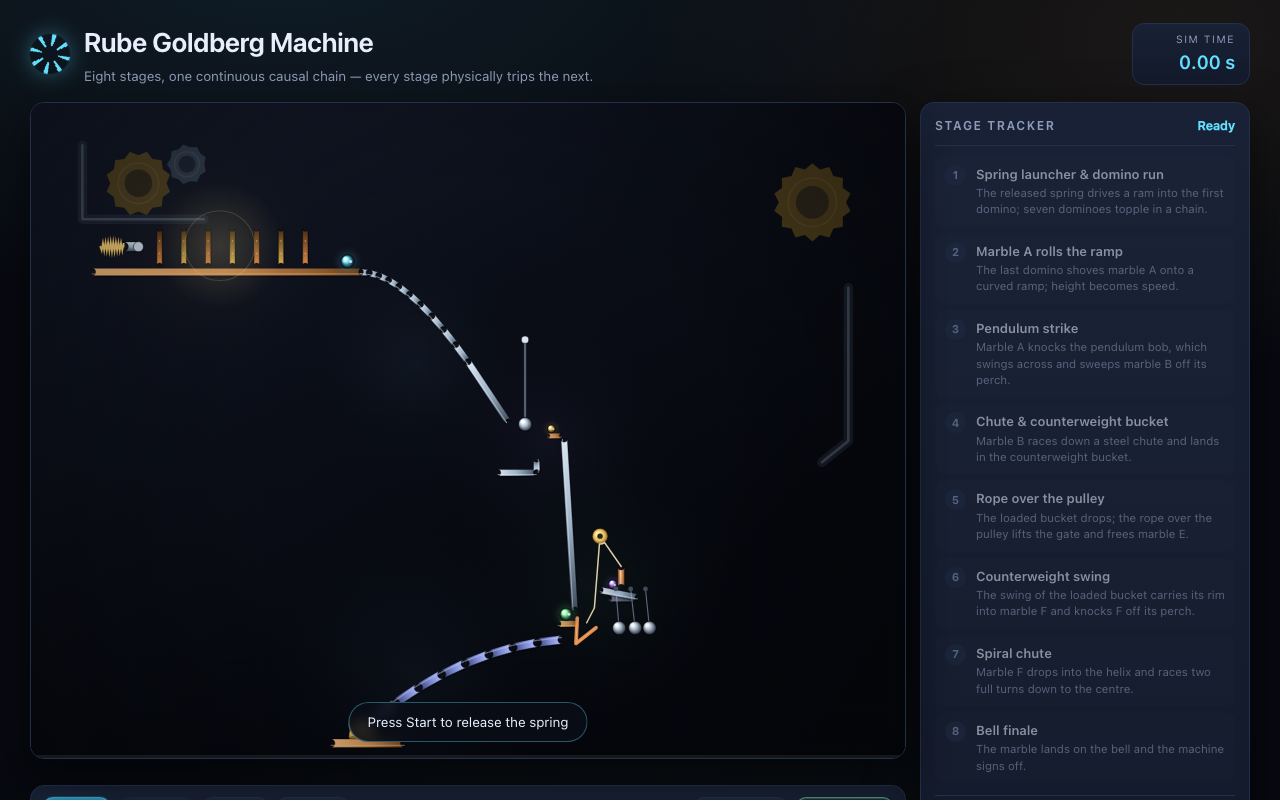
SVG illustration, single-file interactive apps, and multi-file web applications.
In-browser animation, simulation, engineering and authoring tools. This archive currently covers only the tested and archived Tasks 16–20 (5 tasks × 2 models = 10 runs); the remaining tasks have not been run.
The archive does not record a per-run archive date, so these are listed by phase 02 and archive order (group runtime 3:15:56).
Models in one phase receive exactly the same prompt text and resource limits. Prompt versions increase instead of overwriting the original, and comparison stays within one task version.
Pages show the files the models actually delivered: pages can be opened, SVGs can be inspected, and run records keep the call and retry counts.
Human reviews, each AI review version and this website’s own checks are recorded separately; scores are shown side by side with their method and disclaimer, never silently merged.
Scores from different reviewers and rubrics are never merged into a leaderboard; unknown values stay "Not recorded" instead of being inferred.
Type to search; ↑ ↓ to choose, Enter to open
No matching archive records.