Original prompt
Build an app for keeping track of books.
读书追踪应用
4 runs · 15.A.01 · HTML
Preview note: Embedded storage and downloads can be restricted by browser sandboxing; use the standalone view for full behavior.
PROMPT/Phase1_TEST_PROMPTS_BILINGUAL.md · The original prompt is kept verbatim
Build an app for keeping track of books.
构建一个用于追踪书籍的应用。
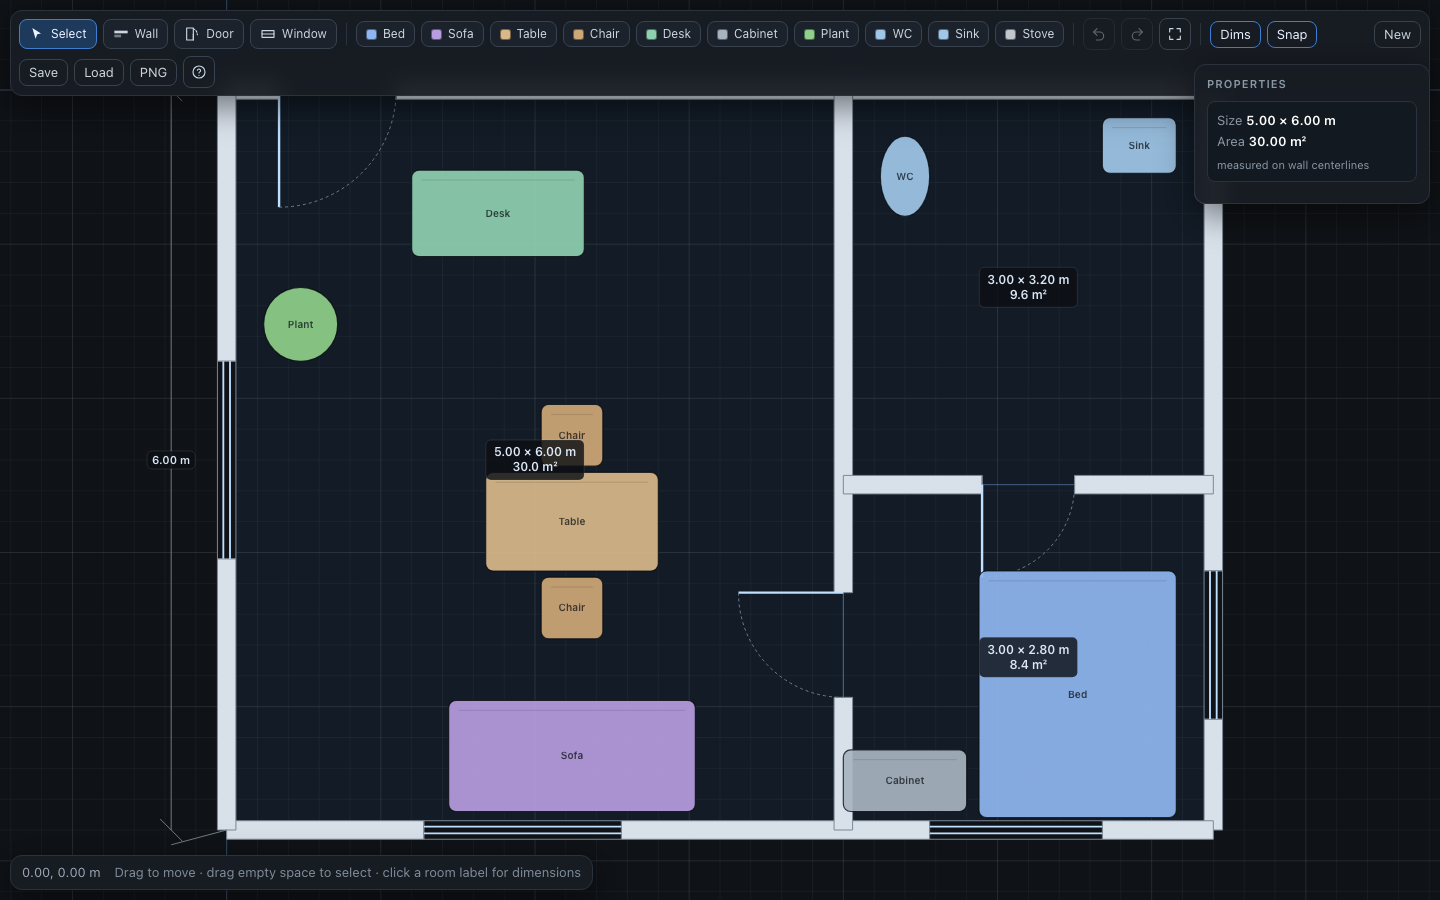
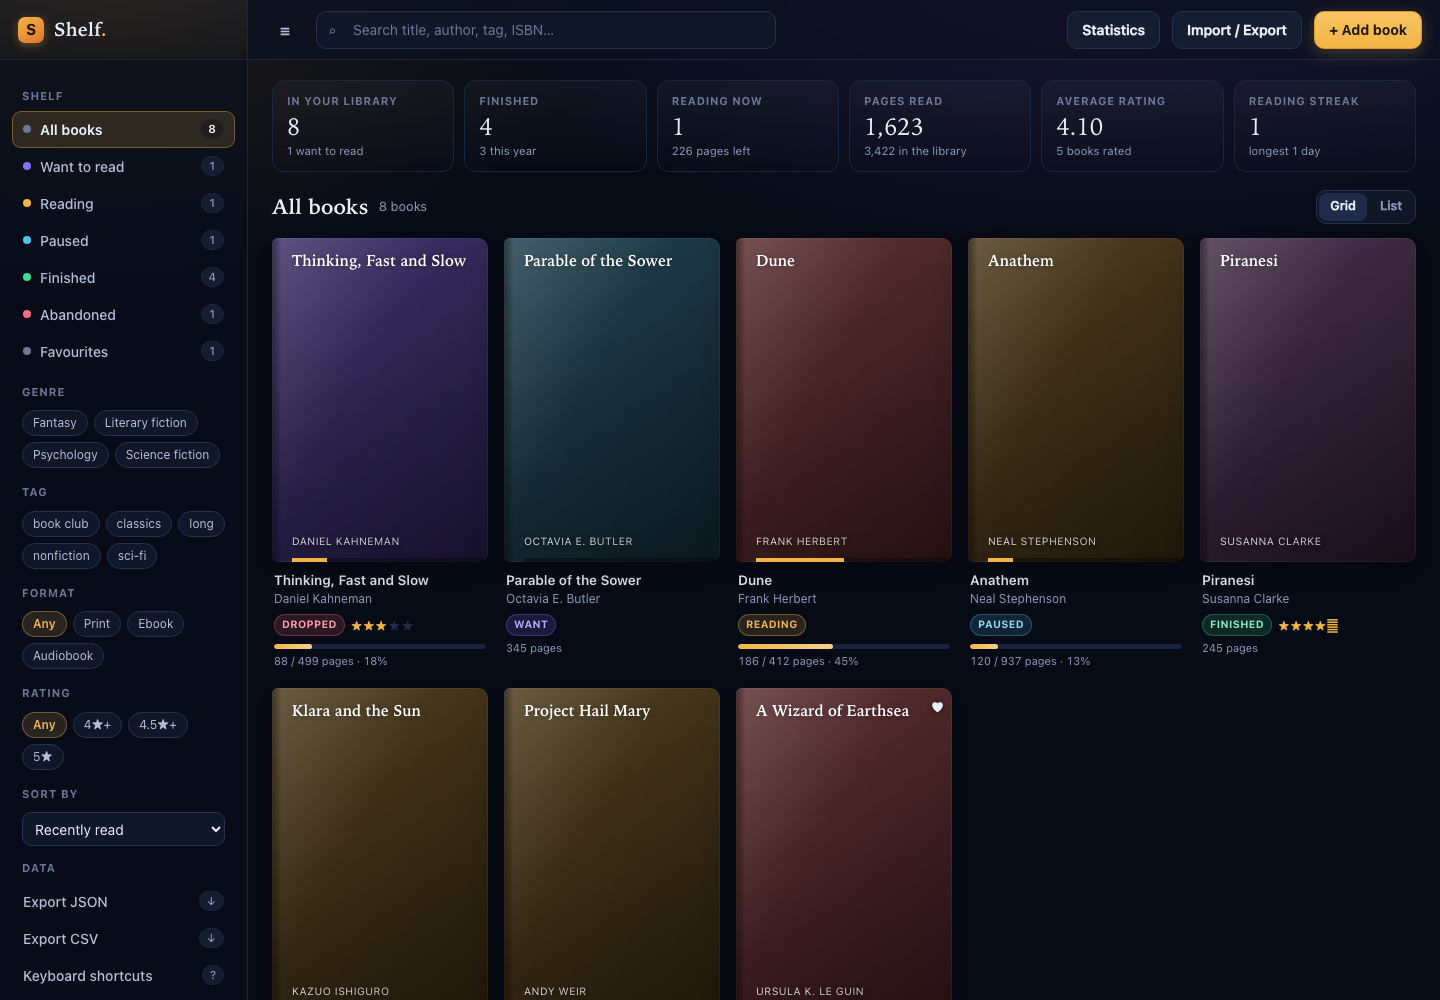
Since the prompt does not constrain platform or scope, a reasonable expected outcome is a working personal-library and reading-progress application. At minimum, users should be able to add, view, edit, and delete books and record title, author, and reading status. A fuller implementation may include page progress, start and finish dates, ratings, tags, favorites, search, filters, sorting, statistics, and local persistence. Status transitions must keep data coherent—for example, finishing should set the finish date and final progress, while reopening should resolve conflicting fields. If import/export exists, data should round-trip and avoid silent duplication. The UI should clearly handle an empty library, zero search results, invalid input, and corrupt storage.
All three results use the same width and the same preview ratio; no model is marked as best.
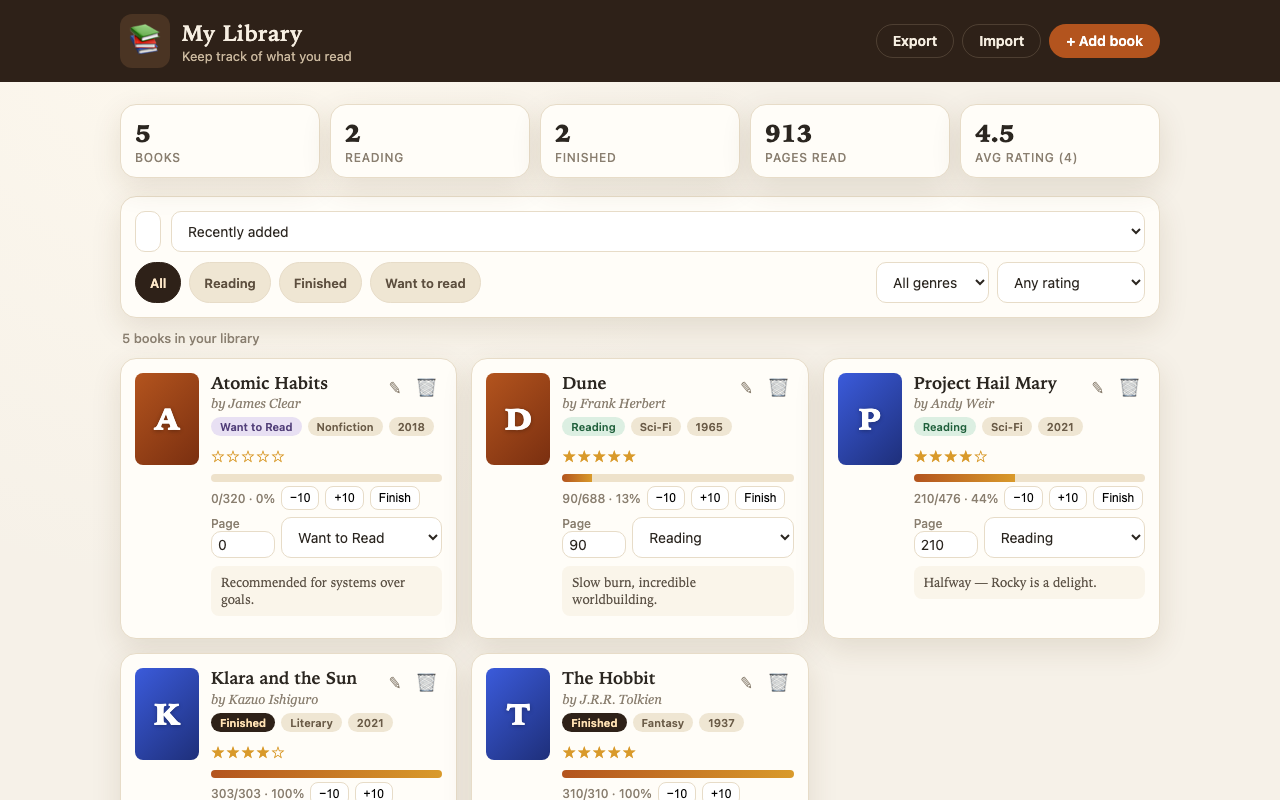
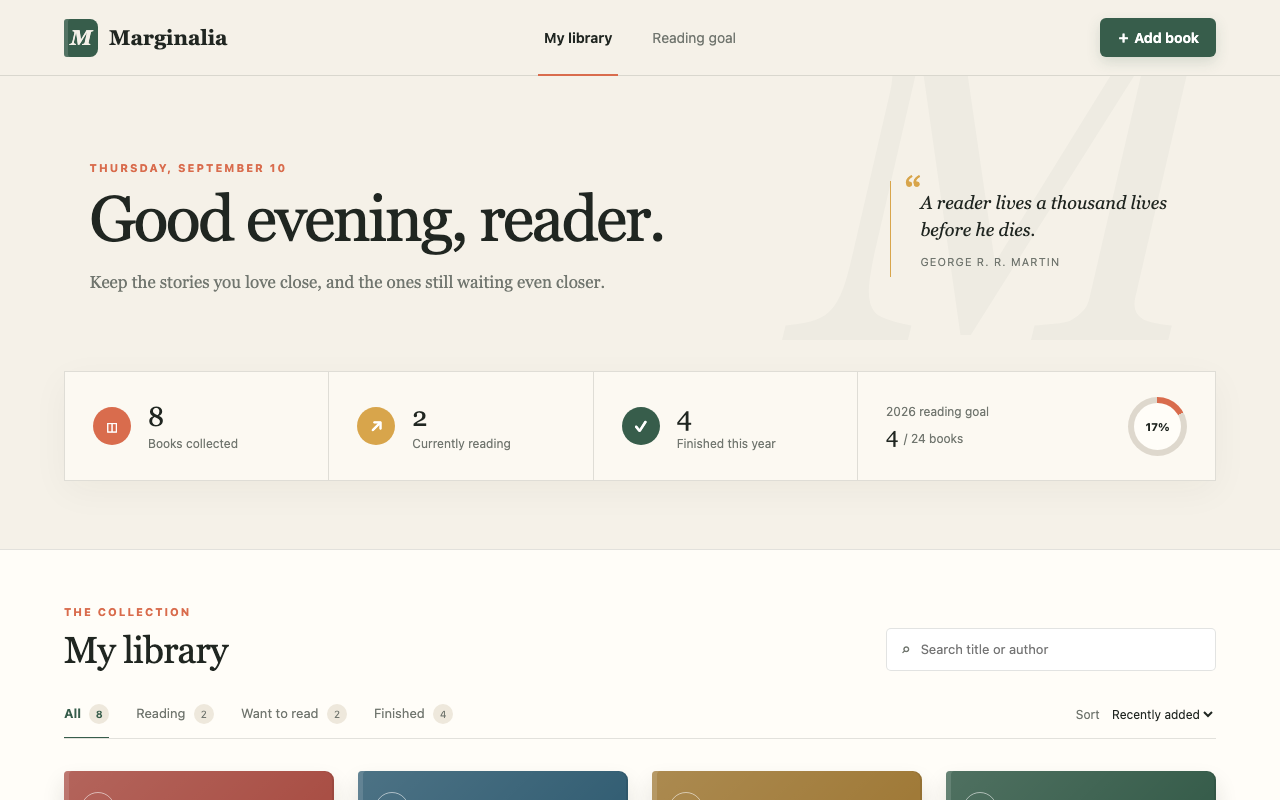
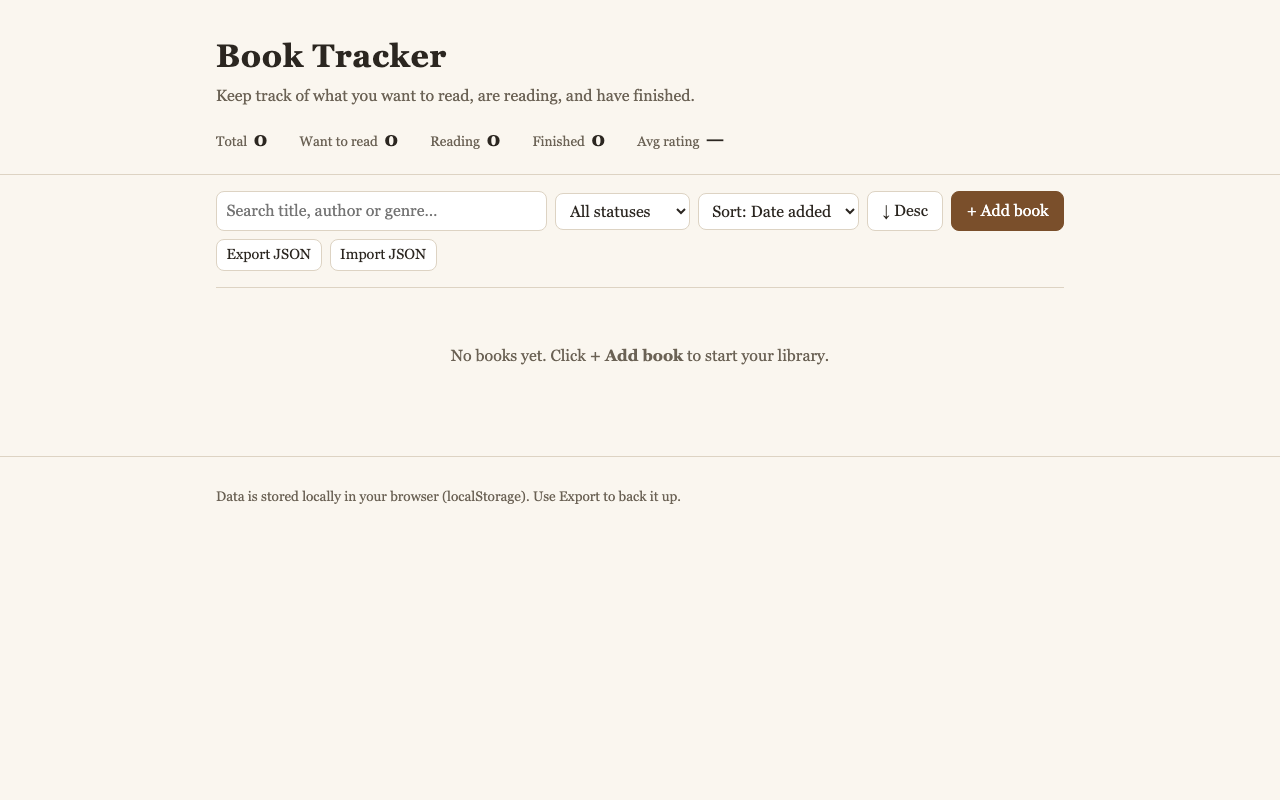
Cross-model comparison must note differences in harness, budget and isolation.
| Metric | DeepSeek-V4.1-Flashrun-deepseek-v4-1-flash-exp-0910-task-15-r1 | Muse Spark 1.3run-muse-spark-1-3-task-15-r1 | GPT-5.6 Solrun-gpt-5-6-sol-task-15-r1 | K3run-k3-task-15-r1 |
|---|---|---|---|---|
| Runtime | 14:26 | 1:35 | 6:52 | 9:06 |
| API calls | 75 | 19 | 8 | 28 |
| Tool calls | 74 | 21 | 6 | 27 |
| Failures / retries | 4 | 0 | 0 | 3 |
| Token throughput | 7.1M | 411.9K | 273.7K | 1.1M |
| AI review | 99/100 | 80/100 | 79/100 | 90/100 |
Two runs of the same task version can be compared side by side.
Type to search; ↑ ↓ to choose, Enter to open
No matching archive records.